



Templates
Data Center Access Policy Template + How to Create one
How to create a data center access policy, with the key components to cover and a template you can download.
Free IT incident report template in Word and PDF with an Excel incident log: severity levels, timeline, root cause, postmortem and a filled-in example.

Content writer, trio.so
An IT incident report template is a ready-made form for recording what happened when an IT service broke or a security event hit: when it was detected, how severe it was, which systems, devices and people were affected, what was done to contain and fix it, the root cause, and who signed it off. This one is for IT and security incidents, such as outages, software and hardware failures, access problems, data mistakes and security events. It is not for workplace injuries or HR complaints.
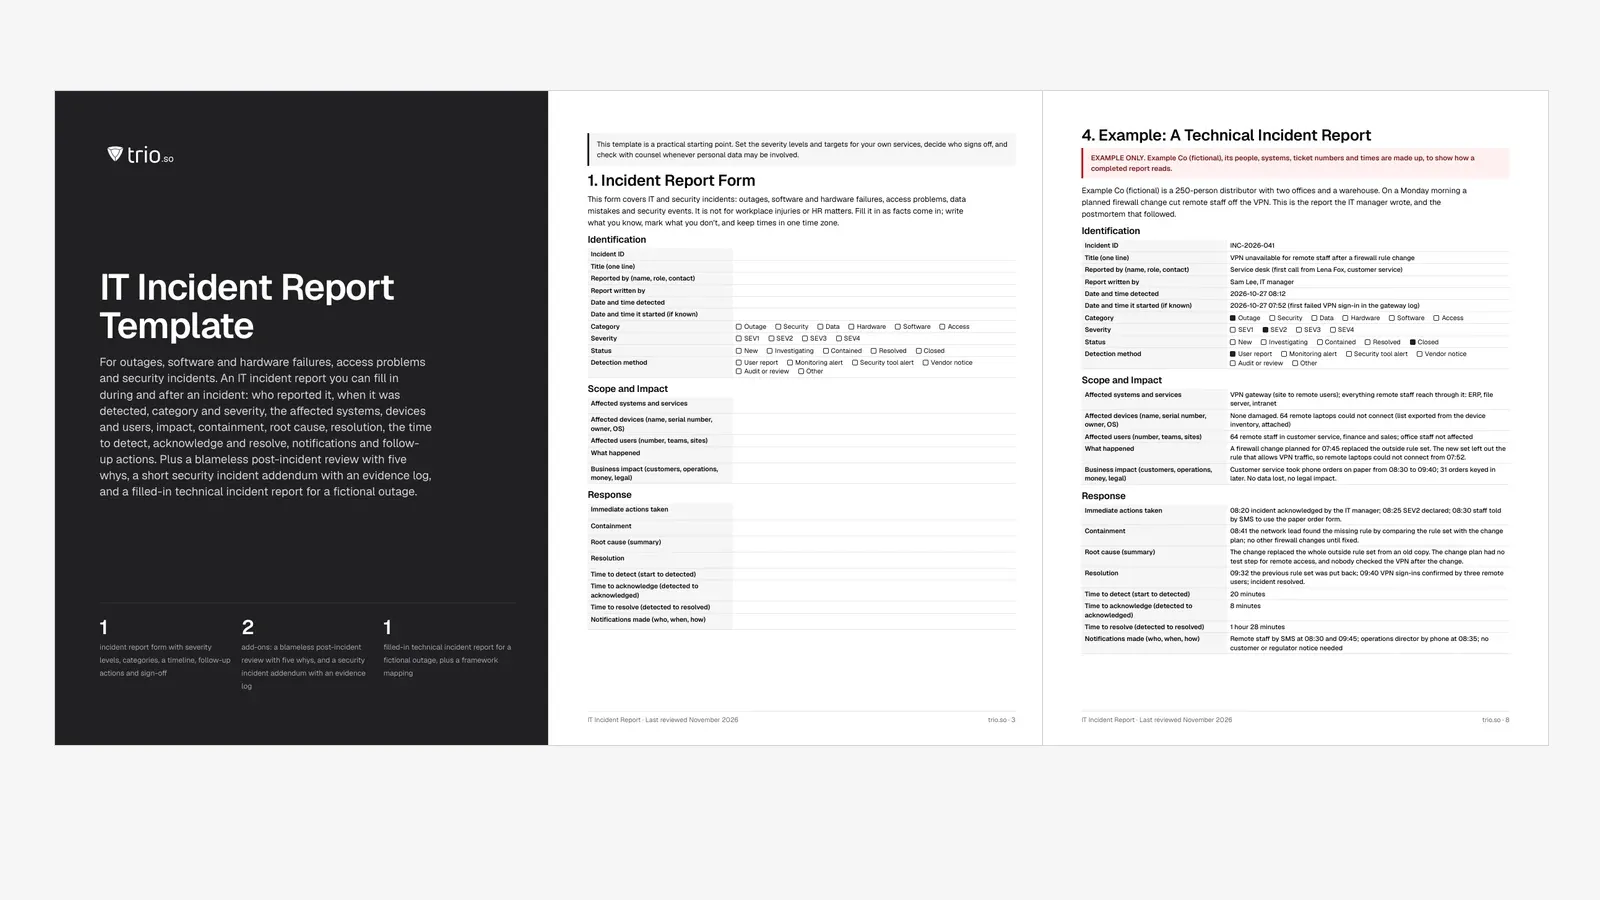
You get a Word report with a fillable form, a blameless post-incident review, a short security incident addendum and a filled-in technical incident report for a fictional outage; the same report as a PDF; and an Excel incident log that works out the time to acknowledge and resolve each incident, flags missed targets, missing postmortems and recurring problems, and sums it all up on a dashboard.
In short
An IT incident is an unplanned interruption to an IT service, a drop in its quality, or a security event that harms or could harm your systems or data. The incident report is the written record of one incident. It answers five questions: what happened, how bad was it, what did we do, why did it happen, and what will we change.
Three documents often get mixed up:
| Document | What it is | When it is written | Who writes it |
|---|---|---|---|
| Incident report | The record of one incident: facts, impact, actions, root cause, notifications and sign-off. | Started when the incident is declared, finished when it is resolved. | The incident owner |
| Incident log | A list of every incident with its severity, owner, status and times, used to spot patterns and missed targets. | One row per incident, kept up to date. | The service desk or IT manager |
| Post-incident review (postmortem) | A blameless look back at one incident: timeline, what went well and badly, root cause and actions. | Within days of a serious incident. | The incident owner with everyone involved |
In ITIL 4 terms, getting the service back belongs to the incident management practice, and finding and removing the underlying cause belongs to problem management. NIST SP 800-61 Rev. 3, the US guidance on cybersecurity incident response revised in April 2025, draws a similar line: incident reports are triaged, incidents are categorized and prioritized, the root cause is analyzed, and lessons learned feed back into improvement.
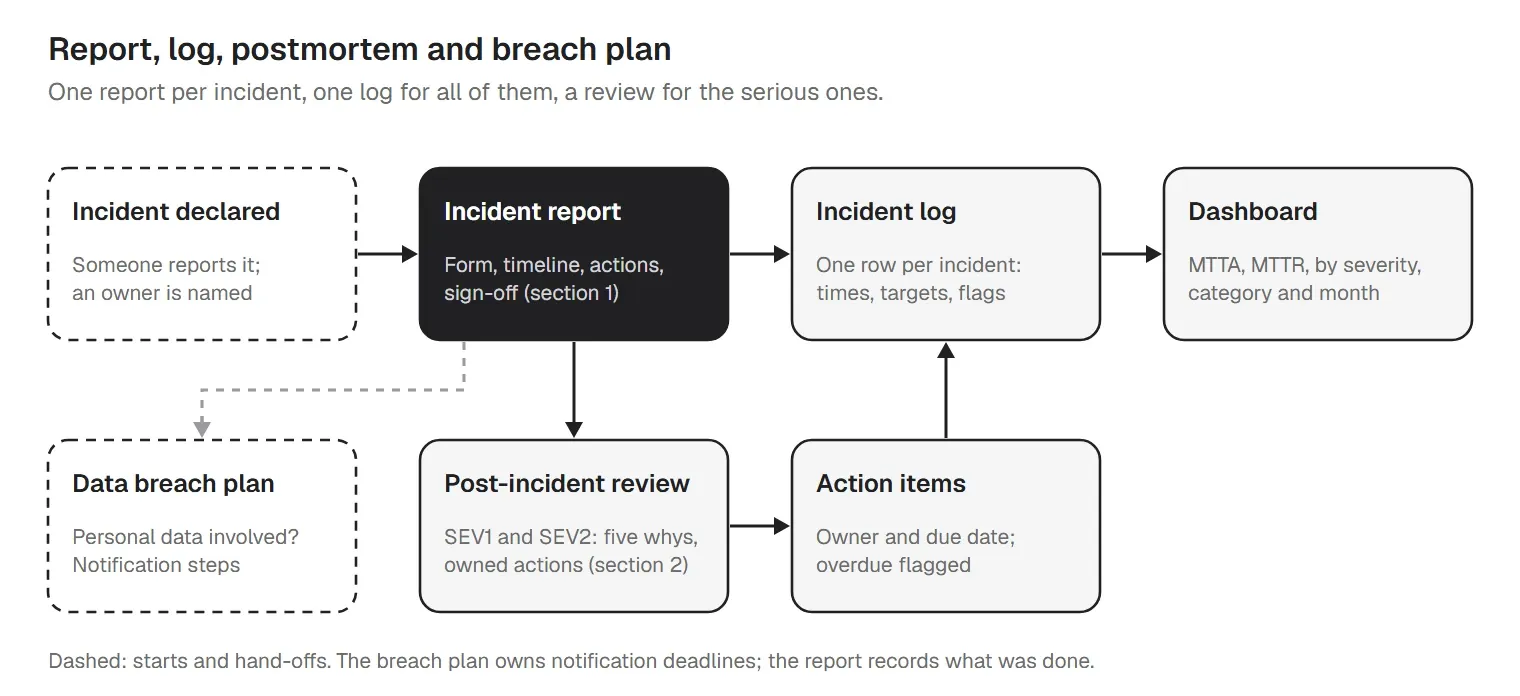
The template's report form has seven parts. Each one matches a question someone will ask later, whether that is your manager, a customer or an auditor:
| Part | Fields |
|---|---|
| Identification | Incident ID, title, who reported it, who wrote the report, when it was detected and when it started, category, severity, status and how it was found. |
| Scope | Affected systems and services; affected devices with name, serial number, owner and operating system; affected users by number, team and site. |
| Impact | What happened, in plain words, and the business impact on customers, operations, money and legal duties. |
| Response | Immediate actions, containment, the root cause in short, and the resolution. |
| Time | Time to detect, time to acknowledge and time to resolve. |
| Communication | Notifications made: who was told, when and how. |
| Follow-up | A timeline, actions with one owner and a due date each, and sign-off by the incident owner and an approver. |
Write the description for someone who wasn't there: a new team member reading it in a year should understand what broke, why, and what changed. Leave out blame and jargon, and mark guesses as guesses until they are confirmed.
Severity decides who gets called and how fast. Many teams use four levels, named SEV1 to SEV4 or P1 to P4. The template's levels and targets are examples, so set your own and agree them with the business:
| Severity | What it means | Acknowledge within | Resolve within | Postmortem |
|---|---|---|---|---|
| SEV1 Critical | A core service is down for everyone, or a security incident is active and spreading, or confirmed data loss. | 15 min | 4 hours | Required |
| SEV2 Major | A core service is down or badly degraded for a group, or a contained security incident with possible data impact. | 30 min | 8 hours | Required |
| SEV3 Minor | A non-core service is down, or a core one has a workaround; a suspicious event under investigation. | 4 h | 72 hours | Optional |
| SEV4 Low | One user or a cosmetic problem, with no business impact. | 24 h | 120 hours | Optional |
Two habits keep severity useful. Decide it on impact, not on how hard the fix looks. And change it when you learn more: a lost laptop logged as SEV3 because it was encrypted becomes SEV2 if it turns out it wasn't. The Excel log reads the targets from its Settings tab and flags every incident that missed its acknowledge or resolve target, including open ones that are running late.
Categories show patterns over time: is it mostly outages, access problems or security events? Six cover most IT teams:
| Category | What it covers | Examples |
|---|---|---|
| Outage | A service or system is down or unusable | Network down, cloud app outage, VPN down |
| Security | An event that harms or may harm confidentiality, integrity or availability | Phishing that worked, malware, account takeover |
| Data | Data lost, corrupted, sent to the wrong place or exposed | Email to the wrong recipient, failed backup, deleted records |
| Hardware | A device or component fails | Disk failure, broken switch, laptop that won't start |
| Software | An app or update misbehaves | Bug after an update, crashing client, failed deployment |
| Access | People can't get in, or have access they shouldn't | Sign-in failures, wrong permissions, locked-out admins |
Some incidents fit two categories. Ransomware that takes the file server down is both a security incident and an outage. Pick the one that drives the response and mention the other in the description. A software incident report or a system outage report uses the same form; the security addendum is for anything with an attacker or exposed data in it.
The report is written during the incident, not afterwards from memory. These steps follow the form:
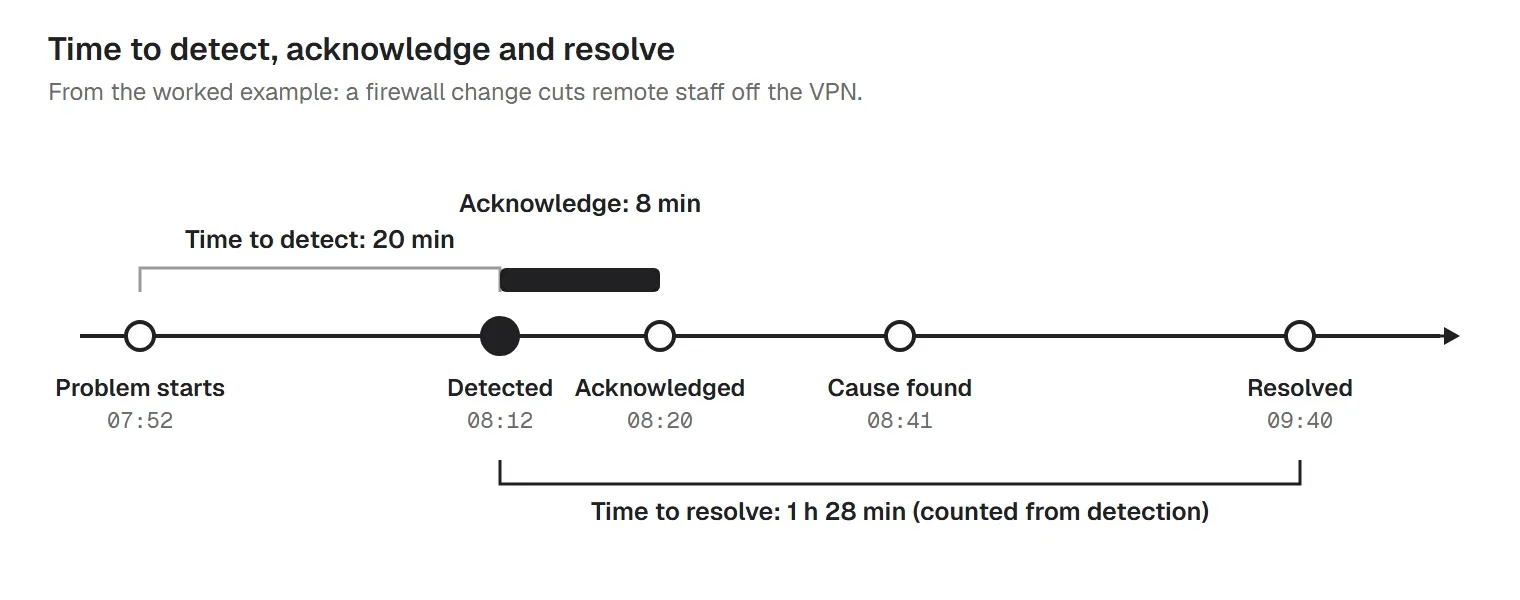
Time to detect runs from the start of the problem to when someone noticed it. Time to acknowledge runs from detection to someone owning the incident, and time to resolve from detection to the service working again. Averaged over many incidents they become MTTD, MTTA and MTTR. MTTR is used for repair, recovery and resolve, so the template says which one it measures: resolve, counted from detection.
Here is the filled-in example from the download, for Example Co (fictional), a made-up 250-person distributor. A planned firewall change on a Monday morning cut remote staff off the VPN:
| Field | Entry |
|---|---|
| Incident ID and title | INC-2026-041: VPN unavailable for remote staff after a firewall rule change |
| Category and severity | Outage, SEV2 |
| Started, detected | 07:52 (first failed VPN sign-in); 08:12 (first call to the service desk) |
| Affected | 64 remote staff in customer service, finance and sales; office staff not affected |
| Business impact | Customer service took phone orders on paper from 08:30 to 09:40; 31 orders keyed in later. No data lost, no legal impact. |
| Containment | 08:41 the network lead found the missing rule by comparing the rule set with the change plan; no other firewall changes until fixed. |
| Root cause | The change replaced the whole outside rule set from an old copy. The change plan had no test step for remote access, and nobody checked the VPN after the change. |
| Resolution | 09:32 the previous rule set was put back; 09:40 VPN sign-ins confirmed by three remote users; incident resolved. |
| Time to detect, acknowledge, resolve | 20 minutes; 8 minutes; 1 hour 28 minutes |
| Notifications | Remote staff by SMS at 08:30 and 09:45; operations director by phone at 08:35; no customer or regulator notice needed |
The full example in the Word file and the PDF adds the timeline with a source for every entry, the postmortem summary, five whys and four actions with owners and dates. Note what it leaves out: no names in the root cause, no "human error" as the answer. The cause is a missing test step and three copies of the rule set, which are things the team can fix. Because the cause was a change, the actions also go into the IT change management template.
The incident report records what happened. The post-incident review, also called a postmortem, a retrospective or an incident response report, asks what to change. The template suggests one for every SEV1 and SEV2, held within about five working days while memories are fresh. It follows four rules:
The review form covers the summary, impact, how the incident was found and how fast, what went well, what didn't, where you got lucky and the contributing factors. The root cause comes from five whys. In the example:
NIST SP 800-61 Rev. 3 treats this as part of improvement: lessons from incident response are identified, analyzed and used to update plans and controls. In practice, that means every finding ends in an action. The log's Action Items tab flags overdue actions, and the Incident Log flags any incident whose severity needs a postmortem when none is marked done within the days you set.
A security incident report uses the same form, plus a one-page addendum with the questions that decide what happens next:
When personal data may be involved, the incident report is where the facts start, and the data breach response plan takes over: it is the playbook for containment, assessment and notification, while this report is the form you fill in along the way. Deadlines are strict. Under NIS2 Article 23, essential and important entities send an early warning within 24 hours of becoming aware of a significant incident, an incident notification within 72 hours and a final report within one month; the breach plan sets out these and the GDPR deadlines. Our data breach notification policy template covers who to tell and when, and what to do after a company data breach walks through the first days. Check every notification decision with counsel.
A report covers one incident; the log shows the pattern. Together they are the incident management template most small IT teams need. The Excel workbook has seven tabs:
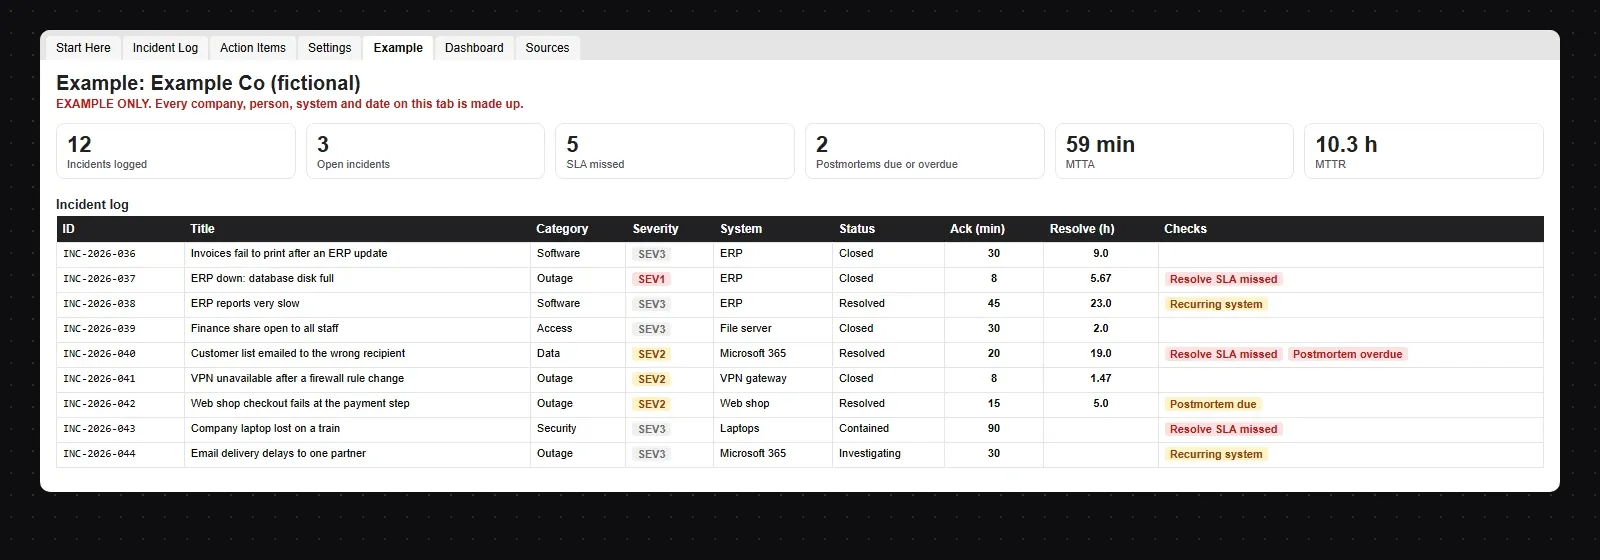
The Example tab shows why the log is worth keeping. Of 12 incidents, 5 missed a target, 1 SEV2 has no postmortem past the deadline, and 2 incidents are flagged as recurring: the ERP system had three incidents in under a month, which is a problem record waiting to be opened. Mean time to acknowledge is 59 minutes and mean time to resolve 10.3 hours, and 2 actions are overdue.
Every major framework expects incidents to be reported, assessed, handled and learned from, with records to show it. The template's mapping table (section 5) points each part of the report to these references:
| Framework | Where incident reporting fits |
|---|---|
| NIST SP 800-61 Rev. 3 | Incident reports triaged and validated (RS.MA-02); incidents categorized and prioritized (RS.MA-03); root cause analysis (RS.AN-03); actions and incident data recorded (RS.AN-06, RS.AN-07); stakeholders notified (RS.CO-02); end of recovery declared and documentation completed (RC.RP-06); improvements identified (ID.IM-03). |
| ISO/IEC 27001:2022 | Annex A 5.24 incident management planning and preparation, 5.25 assessment and decision on events, 5.26 response, 5.27 learning from incidents, 5.28 collection of evidence, and 6.8 information security event reporting. |
| SOC 2 | CC7.3 (events evaluated to decide whether they are incidents), CC7.4 (a defined response: contain, remediate, communicate) and CC7.5 (recovery, root cause and lessons learned). |
| NIS2 | Article 23 reporting of significant incidents: 24 hours, 72 hours, one month. |
| ITIL 4 | The incident management and problem management practices. |
Auditors usually ask for the incident procedure, a sample of incident reports with timelines and sign-off, postmortems with their actions closed, and the log. The mapping is a general guide; your auditor decides what counts for your scope.
trio.so does not detect incidents or watch your network for attacks, and the incident report stays your team's record. What trio.so adds is evidence and context from the device side: which devices were involved, what state they were in, what was done on them, and the actions that contain a lost or compromised device. For that device side, trio.so gives you:
It covers Windows, macOS, Linux, iOS/iPadOS and Android from one console. Plans start at $5 per device.
14-day free trial. No credit card required.
Sources. Last reviewed November 2026. Framework references are general pointers to NIST SP 800-61 Rev. 3, ISO/IEC 27001:2022, the AICPA Trust Services Criteria, the NIS2 Directive and ITIL 4; the wording of every section is ours. trio.so is not affiliated with or endorsed by NIST, ISO, the AICPA or PeopleCert.
trio.so shows each device's owner, serial number, installed apps and patch findings, keeps an audit trail you can export, and locks or wipes lost company-owned devices. Your team still owns the incident report.
Every organization today needs a solution to automate time-consuming tasks and strengthen security. Without the right tools, manual processes drain resources and leave gaps in protection. trio.so is designed to solve this problem, automating key tasks, boosting security, and ensuring compliance with ease.
Every organization today needs a solution to automate time-consuming tasks and strengthen security. Without the right tools, manual processes drain resources and leave gaps in protection. trio.so is designed to solve this problem, automating key tasks, boosting security, and ensuring compliance with ease.





Have questions? We've got answers. This section covers some of the most commonly asked questions related to this topic.
Related
The related industry news, interviews, technologies, and resources.
How to create a data center access policy, with the key components to cover and a template you can download.
Free VPN policy template in Word and PDF: who gets access, approved protocols, MFA, split tunneling and logging, plus an Excel VPN access register.
Free IT offboarding checklist with an Excel tracker: access removal, device return and wipe, admin and BYOD steps, plus sample offboarding emails.
Free application access request form in Word and PDF, with a change and removal form, a filled-in example and an Excel log that flags expired access.
A free IT budget template in Excel with a PDF guide: 11 cost categories, a worked 50-person example, and how to plan, forecast and track your IT budget.
A free IT maintenance schedule in Excel and an IT maintenance plan in Word and PDF: 17 tasks by frequency with owners, a checklist and notice email templates.
Free knowledge transfer plan in Word and PDF with an Excel tracker: KT timeline, handover document per system, checklist and a filled-in IT example.
Discover how a comprehensive Internet Usage Policy can safeguard your organization's security and productivity with our detailed guide.
14-day free trial. No credit card required.
trio.so for MSPs: one console, separate clients